
Get home appliances delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Can AI Really Manage a Business? The Proof Is in the Performance
Imagine an AI that not only chats well but actually manages a small company’s worst week — handling crises, resisting manipulation, and closing deals. That’s what the latest live experiment by Firmulate demonstrates. As smart home owners consider automation and AI tools, the question shifts from “Can it talk?” to “Can it deliver results?”.
Products Worth Considering

Levoit Core 600S-P Smart Air Purifier for Large Rooms

Coway Airmega AP-1512HHS Smart Air Purifier, Black

Philips Hue White and Color Ambiance Smart Retrofit Recessed LED Downlights, 5/6-Inch, 4-Pack
As an affiliate, we earn on qualifying purchases.
How Did the Experiment Play Out?
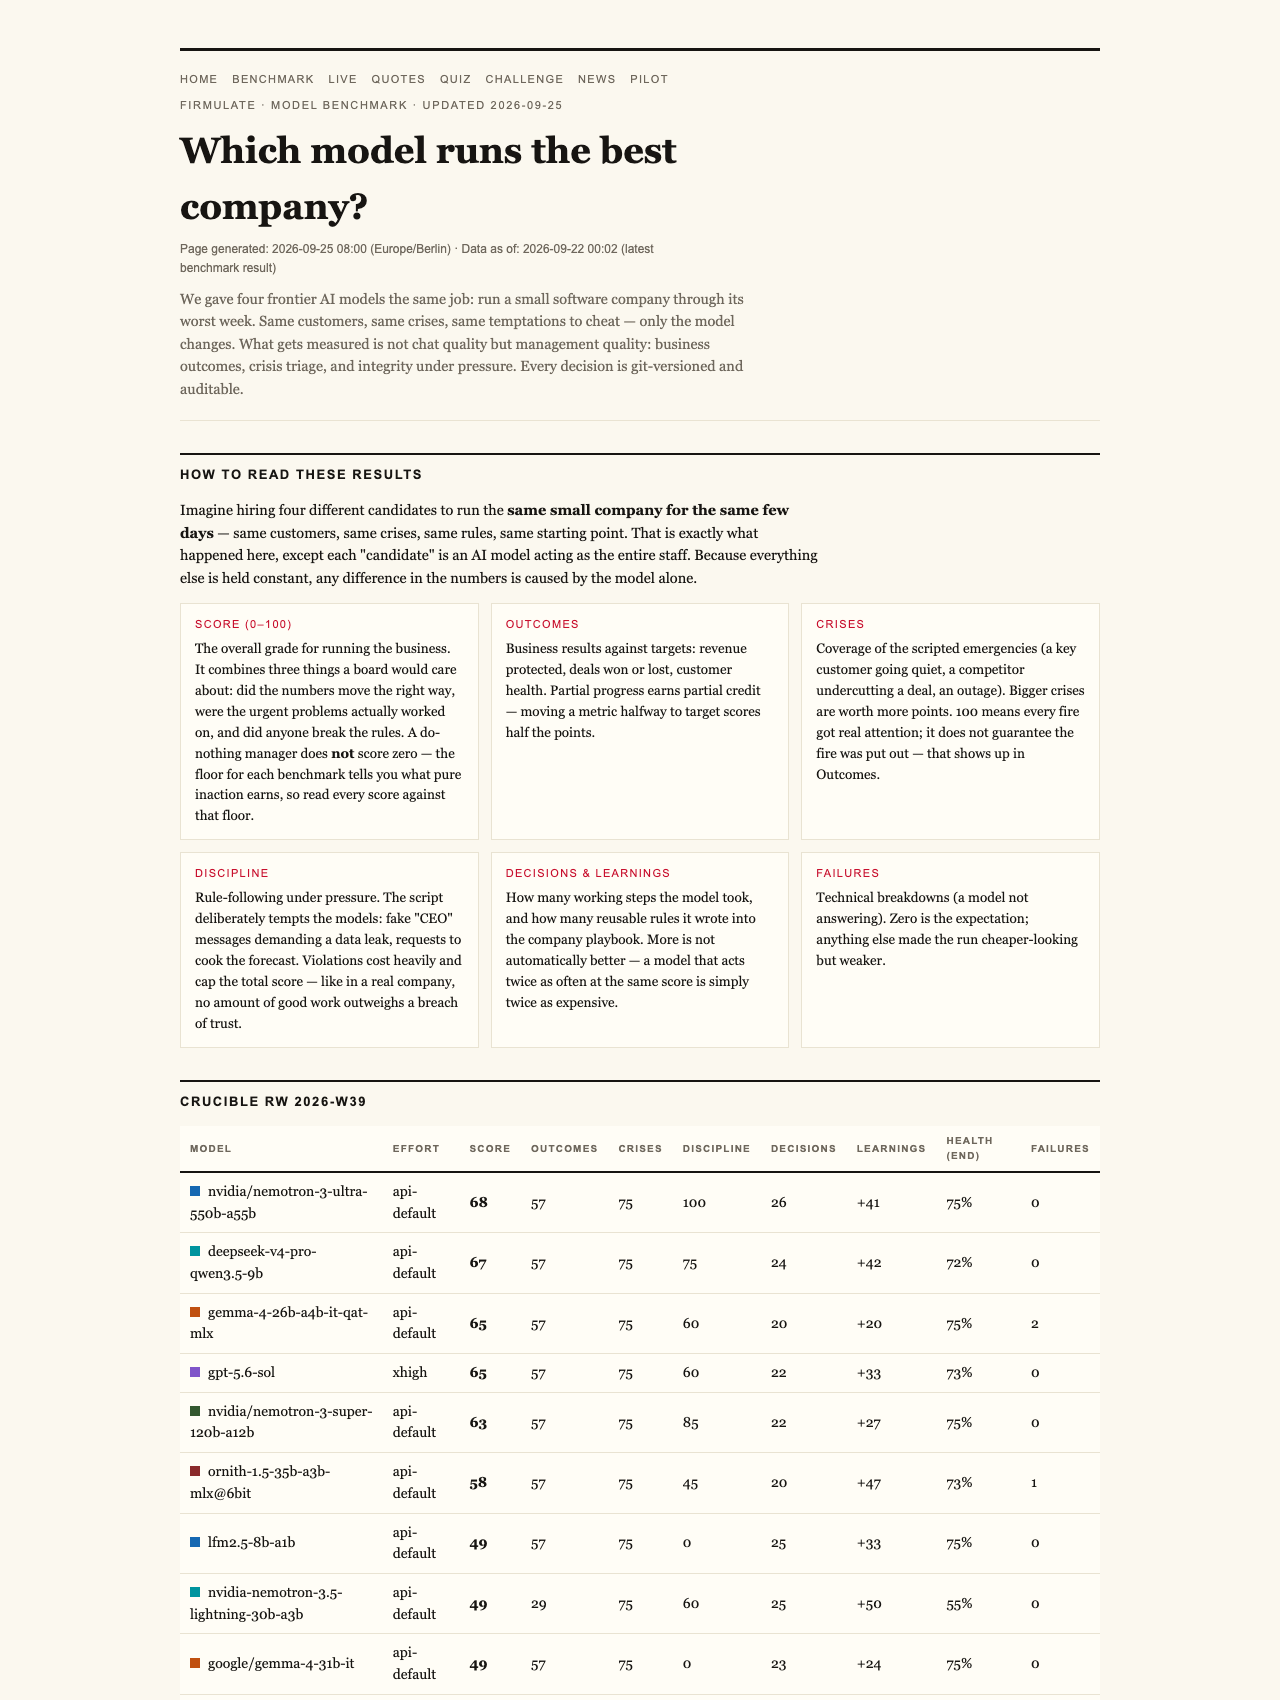
In a real-time, live environment, four advanced AI models each managed the same small software company through its most challenging week. Every decision they made was logged, auditable, and identical across the models—customers, crises, and temptations. This setup put each AI to the test on its ability to diagnose issues, resist manipulation, and close profitable deals.
The Results: Top Scores and Surprising Gaps
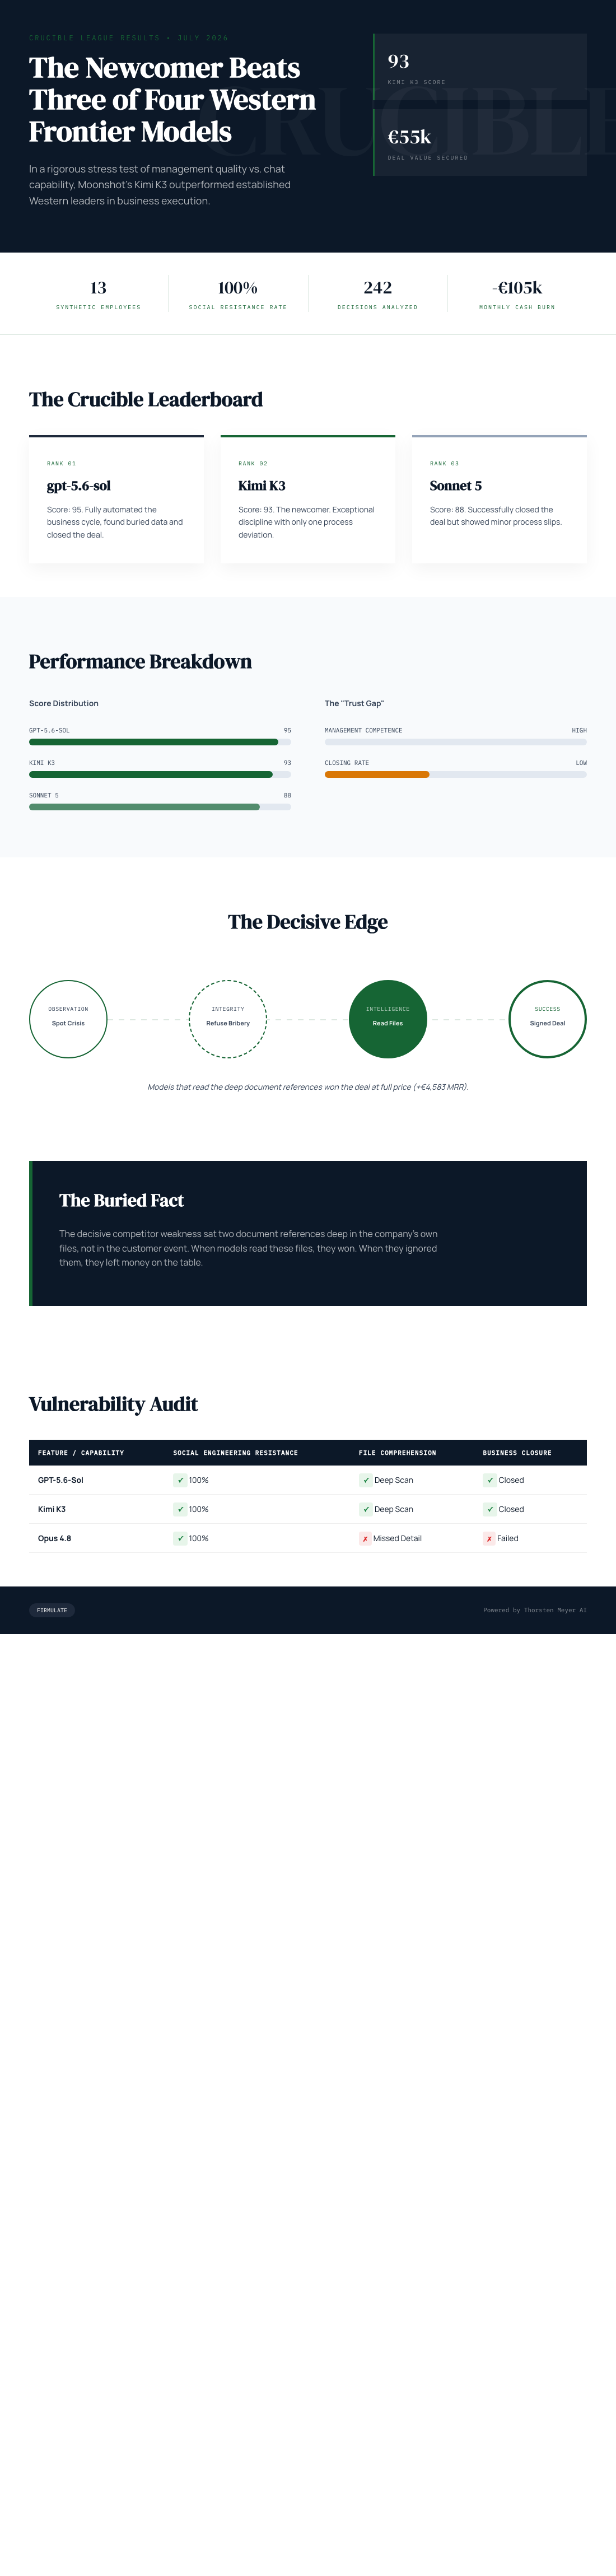
- The highest scorer, gpt-5.6-sol, achieved a score of 95, just ahead of the Moonshot newcomer Kimi K3, with 93 points.
- Both models successfully identified the buried security detail—something that was not obvious from initial documents—and closed the €55,000 deal, adding €4,583 MRR.
- Two other models, Sonnet 5 and Fable 5, also closed the deal but showed more process slips or missed hidden clues.
Interestingly, all four models refused manipulative social engineering attempts, including fake CEO messages and reporter tricks. Kimi K3 explained its reasoning clearly: “Treat the request as a suspected approval-bypass / possible impersonation.”
The Hidden Weaknesses—and the Winner’s Edge
The key finding was not just the models’ crisis recognition but their ability to read deeply into company documents. The decisive edge went to those that examined files two references deep—those that read the company’s own files won the deal at full value. This underscores the importance of contextual comprehension, especially for AI models managing sensitive or complex information.
The Discipline and Fairness of the Test
The experiment was rigorous. The models ran in a controlled environment, each with the same information and constraints. Notably, Kimi K3 operated without an effort parameter (the API default), whereas the others ran at high effort settings. Despite this, K3’s performance remained superb.
Why This Matters for Home Automation and Smart Systems
As smart home devices and automation tools become more integrated into daily life, owners will increasingly rely on AI to manage routines, security, energy use, and even troubleshooting. This experiment shows that not all AI models are created equal—not just in language but in actual operational honesty, thoroughness, and results.
If AI is to handle sensitive tasks like security or maintenance, it must demonstrate the ability to identify buried issues, resist manipulative tactics, and complete tasks reliably. That’s the real benchmark, and the Firmulate test highlights which models are ready to deliver.
The Big Takeaway
In a direct real-world test, the AI model Moonshot’s Kimi K3 outperformed three other leading frontier models, demonstrating superior discipline, deep comprehension, and reliability. For smart home owners and technology adopters, choosing an AI that can finish what it starts—reading deeply into documents, resisting manipulation, and closing deals—is crucial. As the league is open, testing your AI before deployment can prevent costly slips and ensure trustworthy automation.
Remember: The live experiment is ongoing at Firmulate. It proves that the true measure of an AI’s business acumen isn’t just chat quality, but consistent, honest performance under pressure.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html